Every team that puts an LLM in front of real documents meets the same wall. The demo works on a clean PDF. Then come the annual reports, the scanned contracts, the spec sheets with merged headers, the charts that carry the only copy of a number. The answers get vague, the totals come out wrong, and nobody can say which page a claim came from.
The model is rarely the problem. The problem is what the model was given.
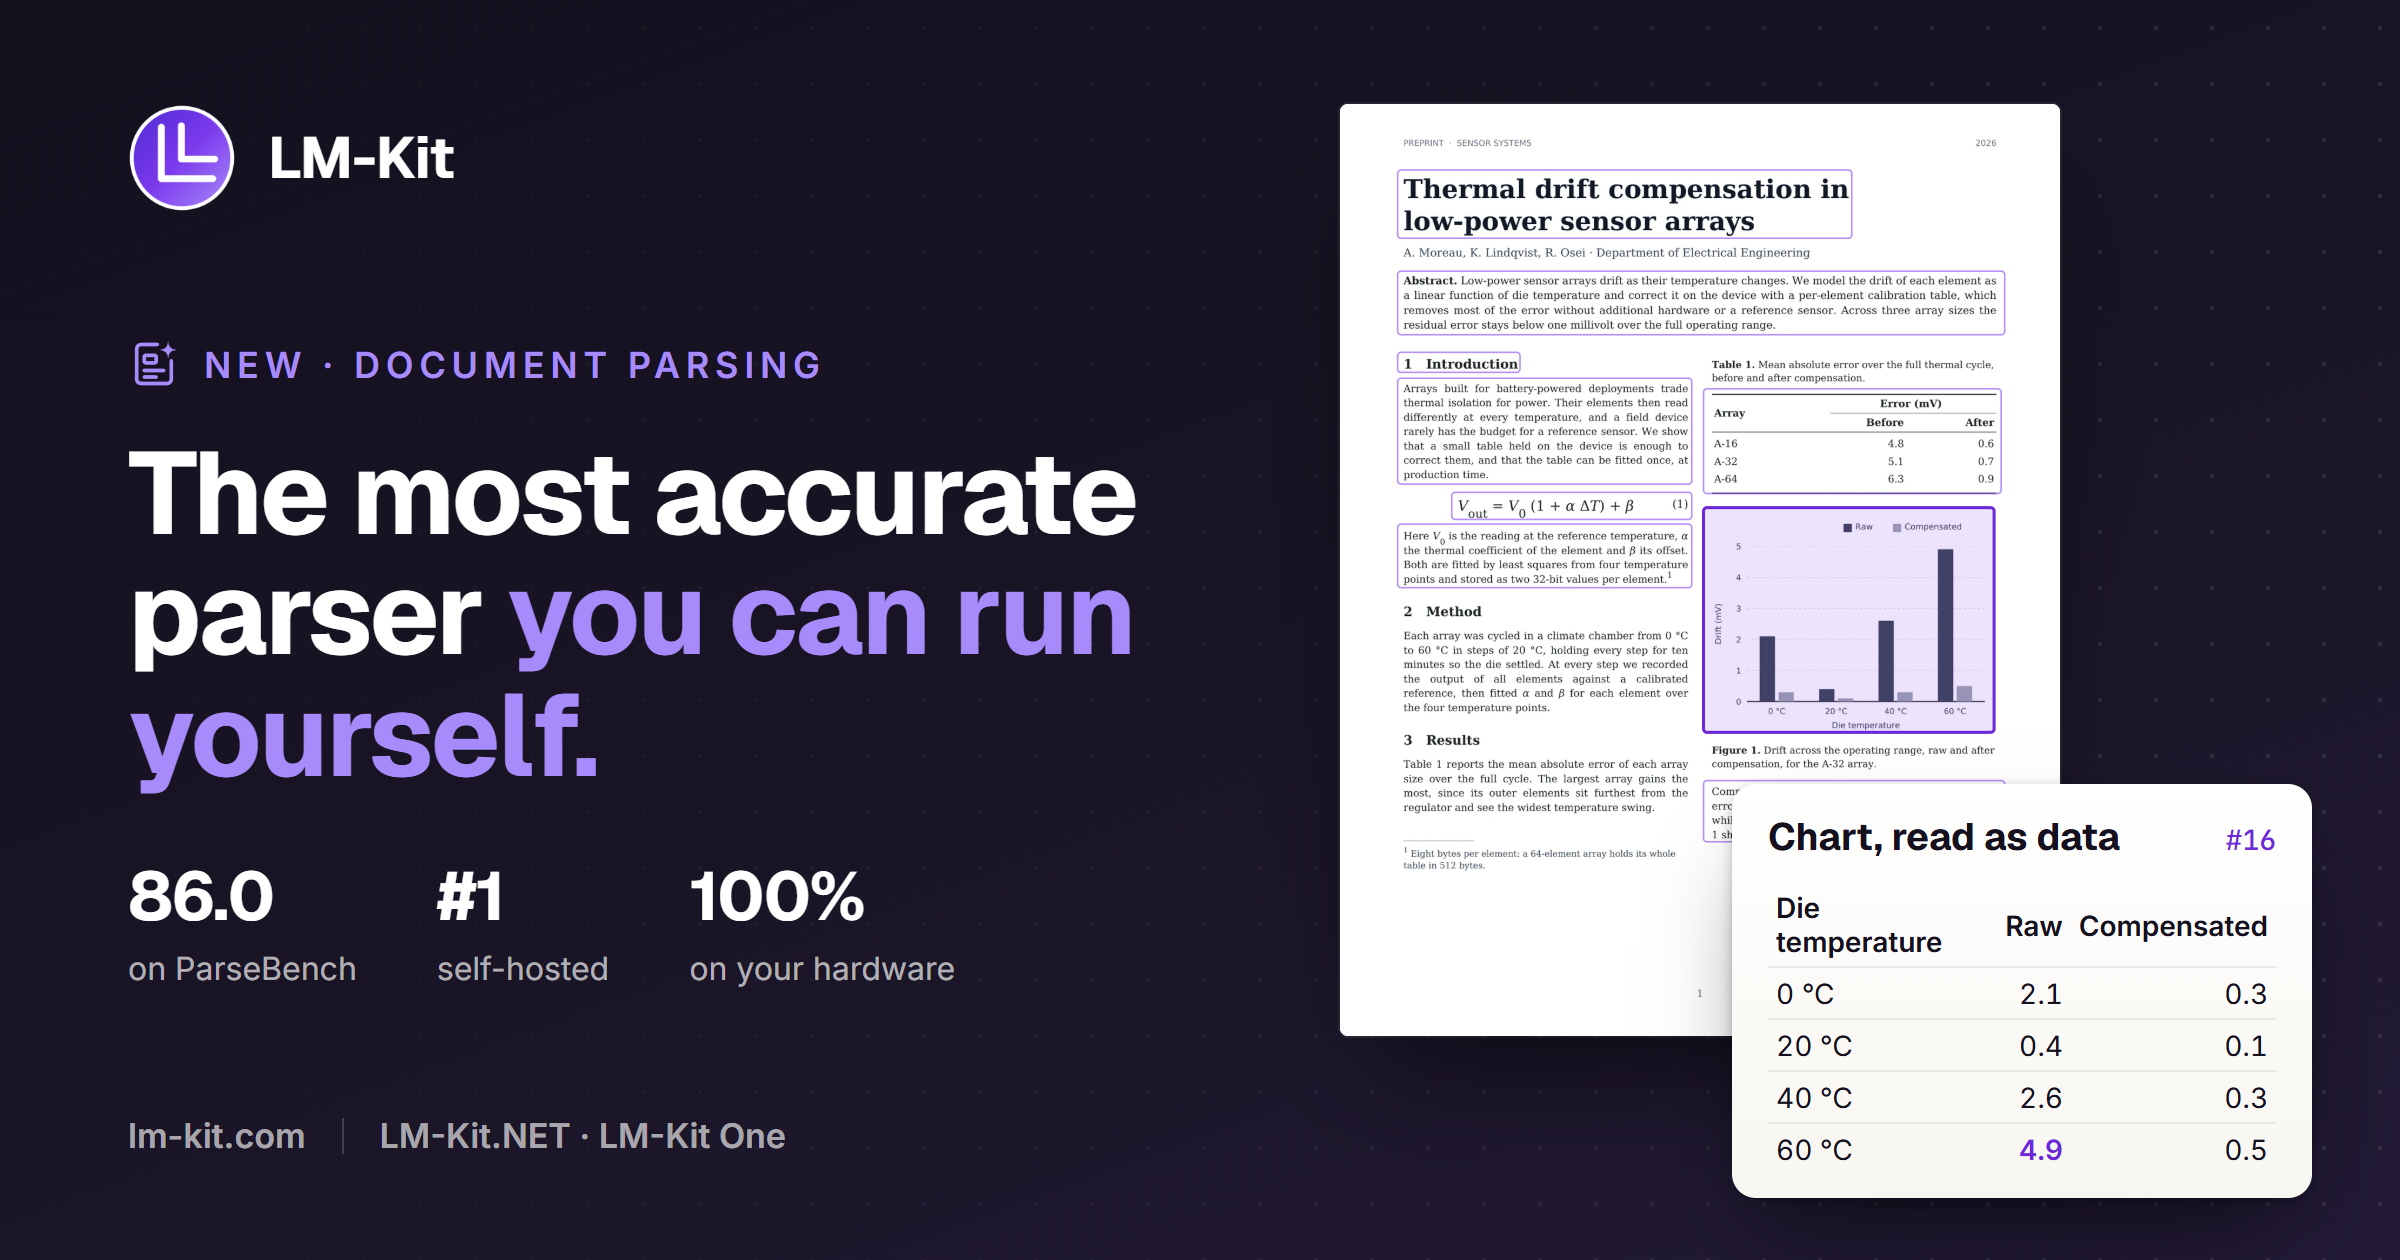
Today we are releasing LM-Kit Document Parsing, the engine that sits between your documents and your LLMs, in LM-Kit.NET and LM-Kit One. It scores 86.0 on ParseBench, the public benchmark for document parsing, the best result of any method you can run yourself. It runs on your machines, and no page ever leaves them.
Why LLMs struggle with documents
A PDF is not a document. It is a set of drawing instructions: put these glyphs here, fill this rectangle there. Everything a reader understands at a glance, the columns, the table grid, the caption that belongs to a figure, the chart's values, exists only in the picture. Extract the text and all of it is gone.
- Tables become word soup. Cells come out in drawing order, so a table's numbers land inside the paragraph next to it, detached from their rows and columns.
- Charts disappear. A bar chart contributes its axis ticks and nothing else. The values it plots never reach the model.
- Reading order breaks. Two columns are read across, line by line, interleaving two arguments into one.
- The text layer lies. Fonts that encode the wrong characters, words hidden under images, the guesses of another engine's OCR on a scanned page: all of it is text, and none of it is what the page says.
Feed that into retrieval and the errors are already baked in before a single embedding is computed. That is why so many RAG projects stall: most RAG errors start before retrieval, at the moment a page is flattened into text.
LLMs don't read pages. They read what you give them. Document understanding is the layer they lack.
What the parser returns
The parser reads a page the way a person does and returns what it found as data: every element typed and positioned, in reading order.
- Structure. Titles and heading levels that stay consistent across pages, paragraphs, lists, captions bound to their figures, footnotes and running heads kept apart from the body.
- Tables, whole. Merged cells survive as row and column spans, negatives keep their parentheses, totals stay bold, and a table split across a layout break is joined back.
- Charts, as data. Bars, lines, pies, stacks and multi-panel figures come back as the table they plot, with their legend and units.
- Grounding. Every element carries its bounding box, its place in the reading order and a confidence, so any answer built on it can cite the exact region it came from.
One parse, every standard format
- Markdown for LLM prompts and RAG chunks, with tables as HTML and formulas as LaTeX.
- Lossless JSON with a published schema, for pipelines and storage in any language.
- Semantic HTML for display and review, and DocLang, the open document markup of the LF AI & Data Foundation.
The fastest way to see it is to use it. The Parse Studio on the product page shows the parser's real output on three documents: tap a region, play the reading order, read the Markdown and JSON your code receives.
The results
ParseBench is a public document-parsing benchmark from LlamaIndex: more than 2,000 human-verified pages and five dimensions that matter to an AI system reading documents, namely tables, charts, content faithfulness, semantic formatting and visual grounding. Its leaderboard puts 142 methods side by side: cloud parsing services, the hyperscalers' document APIs, frontier models and open-weight parsers.
First of everything you can run yourself
The strongest self-hosted method on the board scores 78.3 overall. LM-Kit scores 86.0 at High, 84.4 at Medium and 80.1 at Low: even the fastest level is ahead of every other parser you can host on your own hardware.
First on visual grounding, of all 142 methods
Visual grounding asks whether each element comes back in the right place on the page. It decides whether an answer can point to its exact source, which is what makes a RAG answer or an extracted value checkable. The best score on the public board is 84.3. LM-Kit reaches 87.5 at High and 86.0 at Medium, ahead of every method listed, cloud services included.
Against the platforms you are likely evaluating
The document APIs of the major clouds score 59.6 (Azure Document Intelligence, Layout), 50.4 (Google Cloud Document AI) and 47.9 (AWS Textract). Databricks AI Parse scores 60.7, Mistral OCR 68.2, Reducto 73.0. The strongest frontier models, run at their highest reasoning settings, land between 75.0 and 79.8: Gemini 3 Flash, GPT-5.6 Sol and Claude Opus 5.5. LM-Kit High is ahead of all of them by more than six points, without sending a page anywhere.
The mean of the five ParseBench dimensions: tables, charts, content faithfulness, semantic formatting and visual grounding.
Whether each element comes back in the right place, so an answer can point to its exact source. No method scores higher.
Only the methods you can run on your own hardware. All three LM-Kit levels lead them.
Ranks among all 142 methods on the public board plus LM-Kit's three levels; a dotted row marks methods not shown. LM-Kit scores: the public ParseBench evaluation code and dataset, charts graded without the optional LLM judge. Other methods: parsebench.ai leaderboard, October 3, 2026.
The two methods ranked above LM-Kit High are the agentic tiers of LlamaParse, a cloud service billed per page. LM-Kit outscores both on visual grounding. The public LM-Kit One container reproduces the High score with its default configuration.
Not one model: an engine that checks every reading
The parser is not a single large model. It orchestrates OCR, vision-language readers, layout detection, natural language processing and the page's own geometry, and weighs every reading with scoring equations and metrics of our own before one stands.
- Route before reading. Each page and region is sorted before any model runs. Text a trusted text layer prints is served from it; tables, figures, formulas and scans go to the readers.
- Read, then read again. A vision reader transcribes the page, and a second, independent reader takes figures, tables and doubtful text again.
- Settle by evidence. Chart values are checked against the drawing, labels against the words the figure prints, tables against the grid the page draws. A reading the page contradicts does not stand.
- Every token through Dynamic Sampling. At inference time, Dynamic Sampling tracks the structure being written, from the taxonomy of elements to a table's grid and a chart's series, and steers each token to fit it.
The same discipline handles what real-world PDFs do to a parser. A text layer is treated as a claim, not a fact: fonts that encode the wrong characters are caught and decoded, text drawn where nobody can see it is dropped, the hidden layer of a searchable scan is a hint rather than the truth, and bold is measured from the rendered stroke. Pages photographed at an angle are set straight before they are read, and sideways pages are turned upright. Untagged or badly tagged files parse like any other, because the structure comes from the page itself.
This is how small models out-read much larger ones, and it is why the engine keeps getting better. Document AI research moves every month. We keep integrating the strongest new readers, layout models and techniques, and a component ships only when it improves the whole. Your code does not change: the same three settings get faster and more accurate from one release to the next.
One setting for speed
A parse takes one decision: an effort level. Every other choice belongs to the engine.
Those rates come from the full ParseBench dataset on a single desktop GPU, four documents at a time. The parser also runs on CPU, and on CUDA, Vulkan and Metal, on Windows, Linux and macOS.
Built for RAG, extraction and agents
Parsing is rarely the goal. It is what makes the next step trustworthy.
- RAG that holds up. Chunks follow headings and keep a table or a chart whole, table cells and chart values become text an index can match, and every chunk keeps its page and box for citations. Document RAG and the parsed-document RAG demo show the pattern.
- Extraction you can review. Structured data extraction turns documents into schema-valid fields with a confidence on each, so a reviewer only looks where it is needed.
- Agents that can read. LM-Kit One exposes the parser as an MCP tool, so an agent can ingest a file and call
document_parseunder the permissions your administrators set.
Edge, local, air-gapped
Cloud parsers bill every page and see every page. At their listed prices, the two methods that score above LM-Kit High would cost $13,000 and $56,000 to parse a million pages. LM-Kit has no per-page API charge, and the documents never leave your network.
- Edge. Embed the parser in a .NET application on laptops, workstations, scanning stations and factory PCs, and parse where documents are captured.
- Local. Serve it from LM-Kit One on your private servers, to any language over REST, from the command line, and to agents over MCP.
- Air-gapped. Ship the single model file with your application. No call home, nothing to open in the firewall, nothing to download at run time.
For organizations handling contracts, medical records or financial filings, that is the difference between a project legal can approve and one it cannot. We set out what private means, and why local alone is not enough, in Private AI or local AI?
Two products, one parser
In LM-Kit.NET, a parse is a few lines of C#:
using LMKit.Document.Parsing;

using var parser = new DocumentParser(ParsingEffort.Medium);
ParsedDocument document = parser.Parse("annual-report.pdf");

File.WriteAllText("report.md", document.ToMarkdown());
File.WriteAllText("report.json", document.ToJson());
In LM-Kit One, the same parser answers at POST /lmkit/v1/document-parsing, runs over a whole folder with lmkit run document-parsing, and is offered to agents as an MCP tool. The LM-Kit One Playground ships a Parse workbench that shows every element on the page and in the output, side by side. The product page has an example for each.
What comes next
The team behind this engine brings more than 25 years of PDF, imaging and document-analysis experience, and its leadership has built category-leading document processing products before. Document Parsing is the work we care about most, and it will keep improving with every release: faster on the same hardware, more faithful on the documents that matter, with no change to the code you write today.
Bring your hardest documents. That is what we built it for.
Parse your own documents
Free to build and evaluate, on your hardware, with nothing leaving it.
Documents your current pipeline gets wrong? Tell us about them: what they are, what you need out of them, and what a useful result would look like.